Sound is half of a video. Some video models make sound in the same pass as the picture. Audio models make only the sound, so you control it better, with no microphone or studio. First the three jobs they do, then the families that do them.
Why you shouldn't skip the prep+
Three kinds of audio model
| Kind | You give it | You get back | Use it for |
|---|---|---|---|
| Text to speech (TTS) | Words you type, and a voice | Someone saying them | Voice-overs, narration, dialogue |
| Speech to speech (STS, or voice change) | A recording of someone talking | The same words, the same timing, in a different voice | Keeping your own acting but changing who it sounds like; fixing one voice across clips |
| Music generation | A description: style, speed, mood, length | A new piece of music | A track the video is cut to |
Text to speech is the one you'll use most. Good models let you direct the delivery, not just the words: add pauses, laughs or whispers, and they read the emotion from the line.
Speech to speech keeps everything about how something was said (the timing, the pauses, the emotion) and swaps the voice. Record a line yourself, the way you want it acted, and turn it into your character's voice. There's more on both in TTS and speech-to-speech.
Music generation writes a new track from a description, like “chill house, 110 beats a minute, a drop at 8 seconds, 15 seconds long”. Make the music first, then cut the video to its beat.
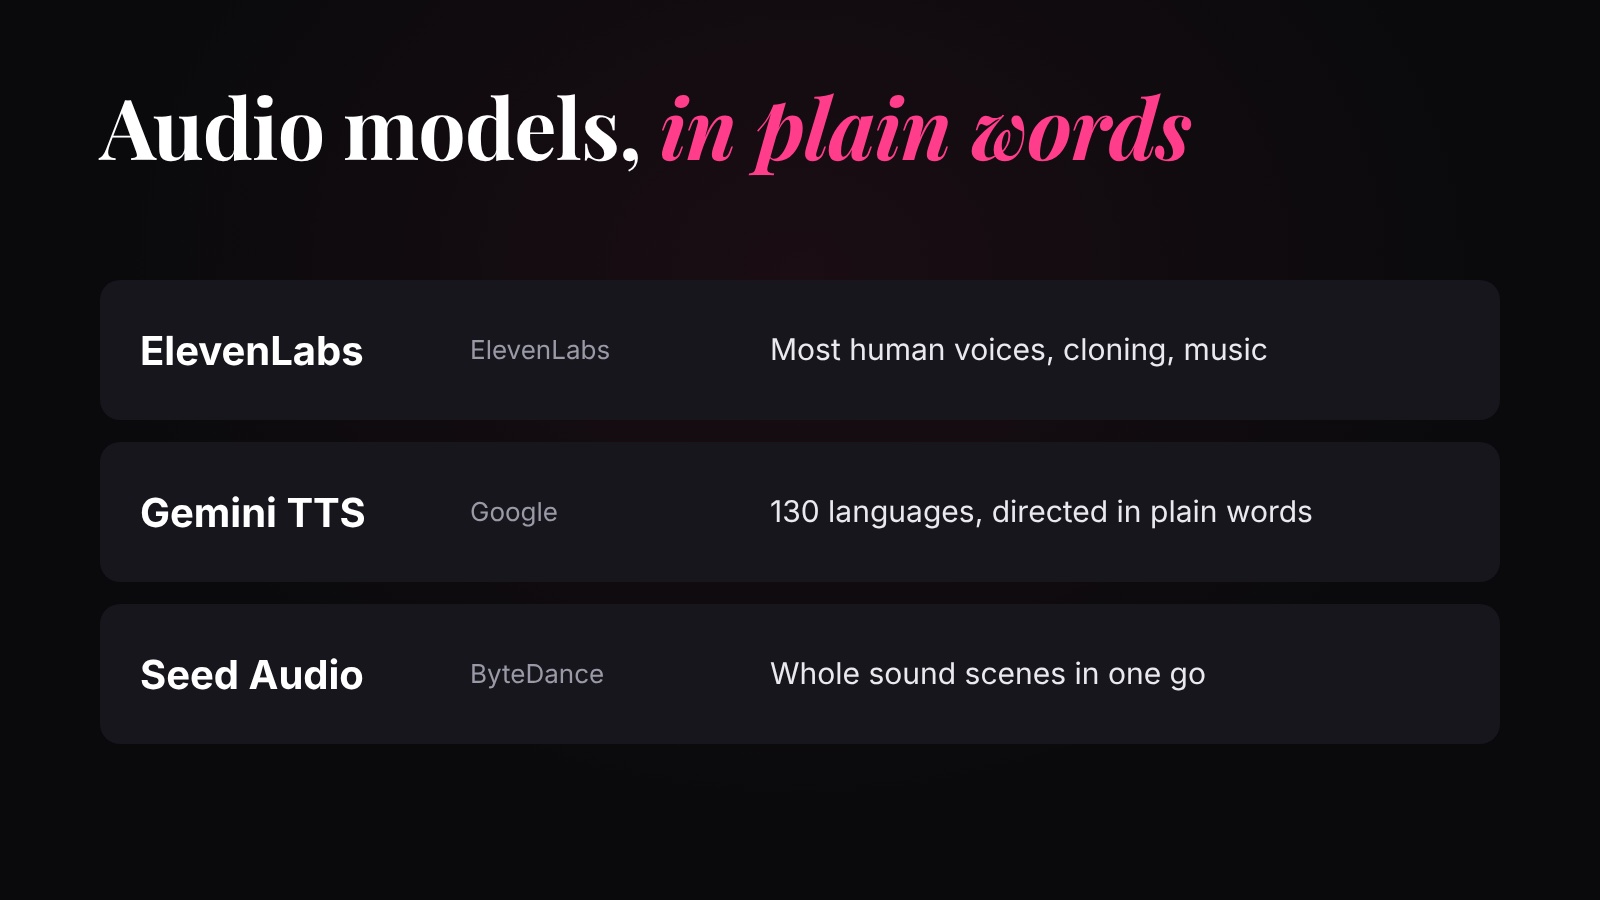
ElevenLabs
An AI voice company. On OpenDirector: ElevenLabs TTS v4 (most natural), v4 Turbo (faster, cheaper), v3, the ElevenLabs Voice Changer (speech to speech) and ElevenLabs Music v2.5.
| Good at | Watch out for |
|---|---|
| Voices that sound very human, with emotion you steer using tags like [whispering] or [laughing]. | On long reads the tone can shift partway through. Generate a paragraph at a time and check. |
| Copying a voice, and changing the voice of a recording (Voice Changer). | It costs more than Gemini for the same line. |
| All three jobs in one place: speech, voice change and music. | Music is new: judge it by your own tests. |
Pick it when you want the most natural, emotional voice, a cloned voice, or music.
Gemini TTS (Google)
Google's text-to-speech model. On OpenDirector: Gemini 3.8 Flash TTS. You give it the words and describe how they should sound.
| Good at | Watch out for |
|---|---|
| About 130 languages and regional accents, including Hindi and other Indian languages. | Speech only: no music, no sound effects, no voice change. |
| Directing the delivery in plain words, with laughs, sighs and pauses inside the line. | Fewer ready-made tools around it than ElevenLabs. |
| Very low price for long scripts. | Few independent listening tests so far. |
Pick it when you want good, affordable speech in many languages or accents.
Seed Audio (ByteDance)
ByteDance's audio models. On OpenDirector: Seed Audio 1.0, which makes a whole sound scene (people talking, sound effects, background and music together), and Seed Speech for text to speech.
| Good at | Watch out for |
|---|---|
| A complete sound scene in one go, up to about 2 minutes. | Fewer languages than Gemini or ElevenLabs (about 20). |
| Copying a voice from a very short sample. | Little official English documentation, so test first. |
| Fast, with 200+ ready-made voices. | Less control over each separate sound than making them one by one. |
Pick it when you want a full soundscape quickly, or a quick cloned voice.
Which one should I use?
| You want | Use |
|---|---|
| The most natural English voice-over | ElevenLabs TTS v4 |
| Speech in Hindi or another language, cheaply | Gemini 3.8 Flash TTS |
| To keep your acting but change the voice | ElevenLabs Voice Changer |
| A music track to cut to | ElevenLabs Music v2.5 |
| A whole sound scene in one pass | Seed Audio 1.0 |
How to open each one on OpenDirector
- Go to app.opendirector.co and sign in.
- Click Audio in the top bar.
- Pick Text to Speech or Voice Change, then the model (for example ElevenLabs TTS v4) from the list.
- For speech, type your lines and pick a voice. For voice change, upload your recording and pick the new voice. For music, describe the track and its length.
- Check the price on the button, then press Generate. Your result lands in your library.
Or jump straight to a model: ElevenLabs TTS v4 · ElevenLabs v4 Turbo · ElevenLabs Voice Changer · ElevenLabs Music v2.5 · Gemini 3.8 Flash TTS · Seed Audio 1.0 · Seed Speech.
What each one costs is on the price comparison.
Quick answers
What is TTS?
Text to speech: you type words and the model says them in a voice you pick.
What is STS or voice change?
Speech to speech: you give it a recording and get the same words, with the same timing and emotion, in a different voice.
Can AI make music for my video?
Yes. Describe the style, speed, mood and length, and a music model writes a new track. Make it first, then cut the video to its beat.
Which voice model is best for Indian languages?
Gemini 3.8 Flash TTS handles Hindi and many Indian languages well and costs little. ElevenLabs is the choice when the most natural voice matters most.